Disimula – AI-written missions
A queue, a worker that calls Claude, and three separate sessions - writer, evaluator and translator - with layered defences against prompt injection.
Writing good missions is the hard part of the game: they must be doable, discreet, funny, safe for whoever is playing, and different from each other. Disimula uses Claude to write them in two places:
- Admins create new themes, or new variants of an existing theme, for everybody's catalog.
- Organizers generate their own private sets, paying with AI credits.
Either way, every set passes an AI evaluator and then a human decision before it reaches a game. That human check has limits, described below: an admin approves a catalog set from a sample of five so they can still play it, and translations of approved missions join without a second review.
A queue, not a request
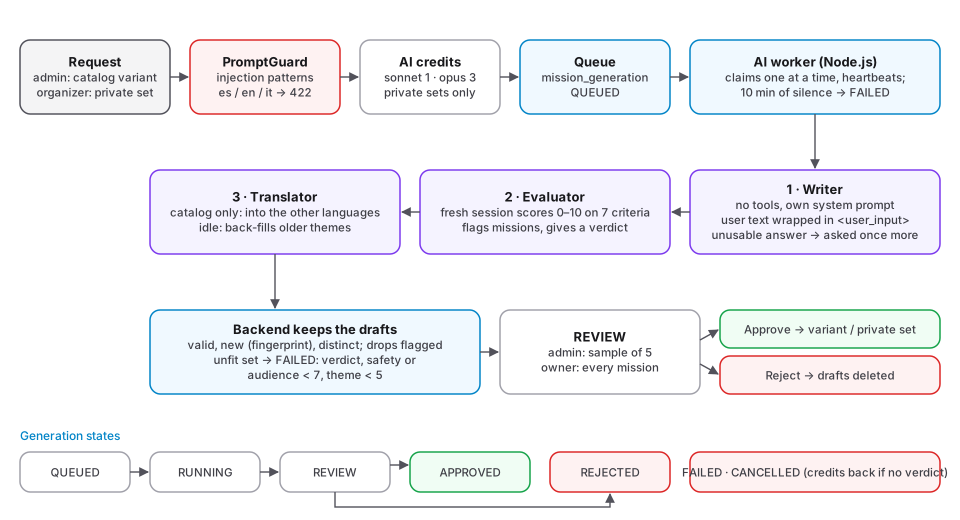
Generation takes minutes, so it is a job, not an HTTP call:
- The request is validated and screened by
PromptGuard(below), credits are charged for a private set, and a row is queued inmission_generation. - The AI worker (
frontend/automation/worker.ts, its own container) pollsPOST /missions/worker/claimevery 10 seconds and takes one job at a time. It authenticates with a bearer token that only grants access to the worker endpoints. - While it runs it sends a heartbeat. A running generation whose worker goes silent for 10
minutes fails. On
SIGTERM(a deploy) the worker releases its job back to the queue, and compose gives it 60 seconds to do so. - It hands in the missions and the evaluation; the backend filters them and moves the generation to
REVIEW.
Only one unfinished generation per theme (409 generation_already_active) and one per organizer,
so a burst of clicks never multiplies the cost.
Each model call is isolated
Every call to Claude is a single, self-contained session, with the model chosen by whoever asked (Sonnet or Opus):
- No tools at all. The model can only produce text.
- A system prompt of its own for each task (writing, evaluating, translating).
- Bounded: a few turns at most and a timeout, and it is killed if the generation is cancelled or the worker stops.
- No secrets in reach. The worker's own
WORKER_TOKENand anything else it holds never reach a session that reads user-written text. - The worker runs in its own container, as a non-root user.
Three sessions, three jobs
1. Writer
The prompt (automation/prompt.ts) carries the rules of a good mission, the output contract
({"missions": [...]}), the theme's prompt and examples, the variant's own prompt, what the
difficulty means in concrete terms, the audience (all, teens, adults, each with an explicit
list of what it rules out) and, for catalog themes, the theme's existing missions to avoid. It asks
for a few more than requested, since the backend drops repeats. An unusable answer is asked for once
more in the same session.
2. Evaluator
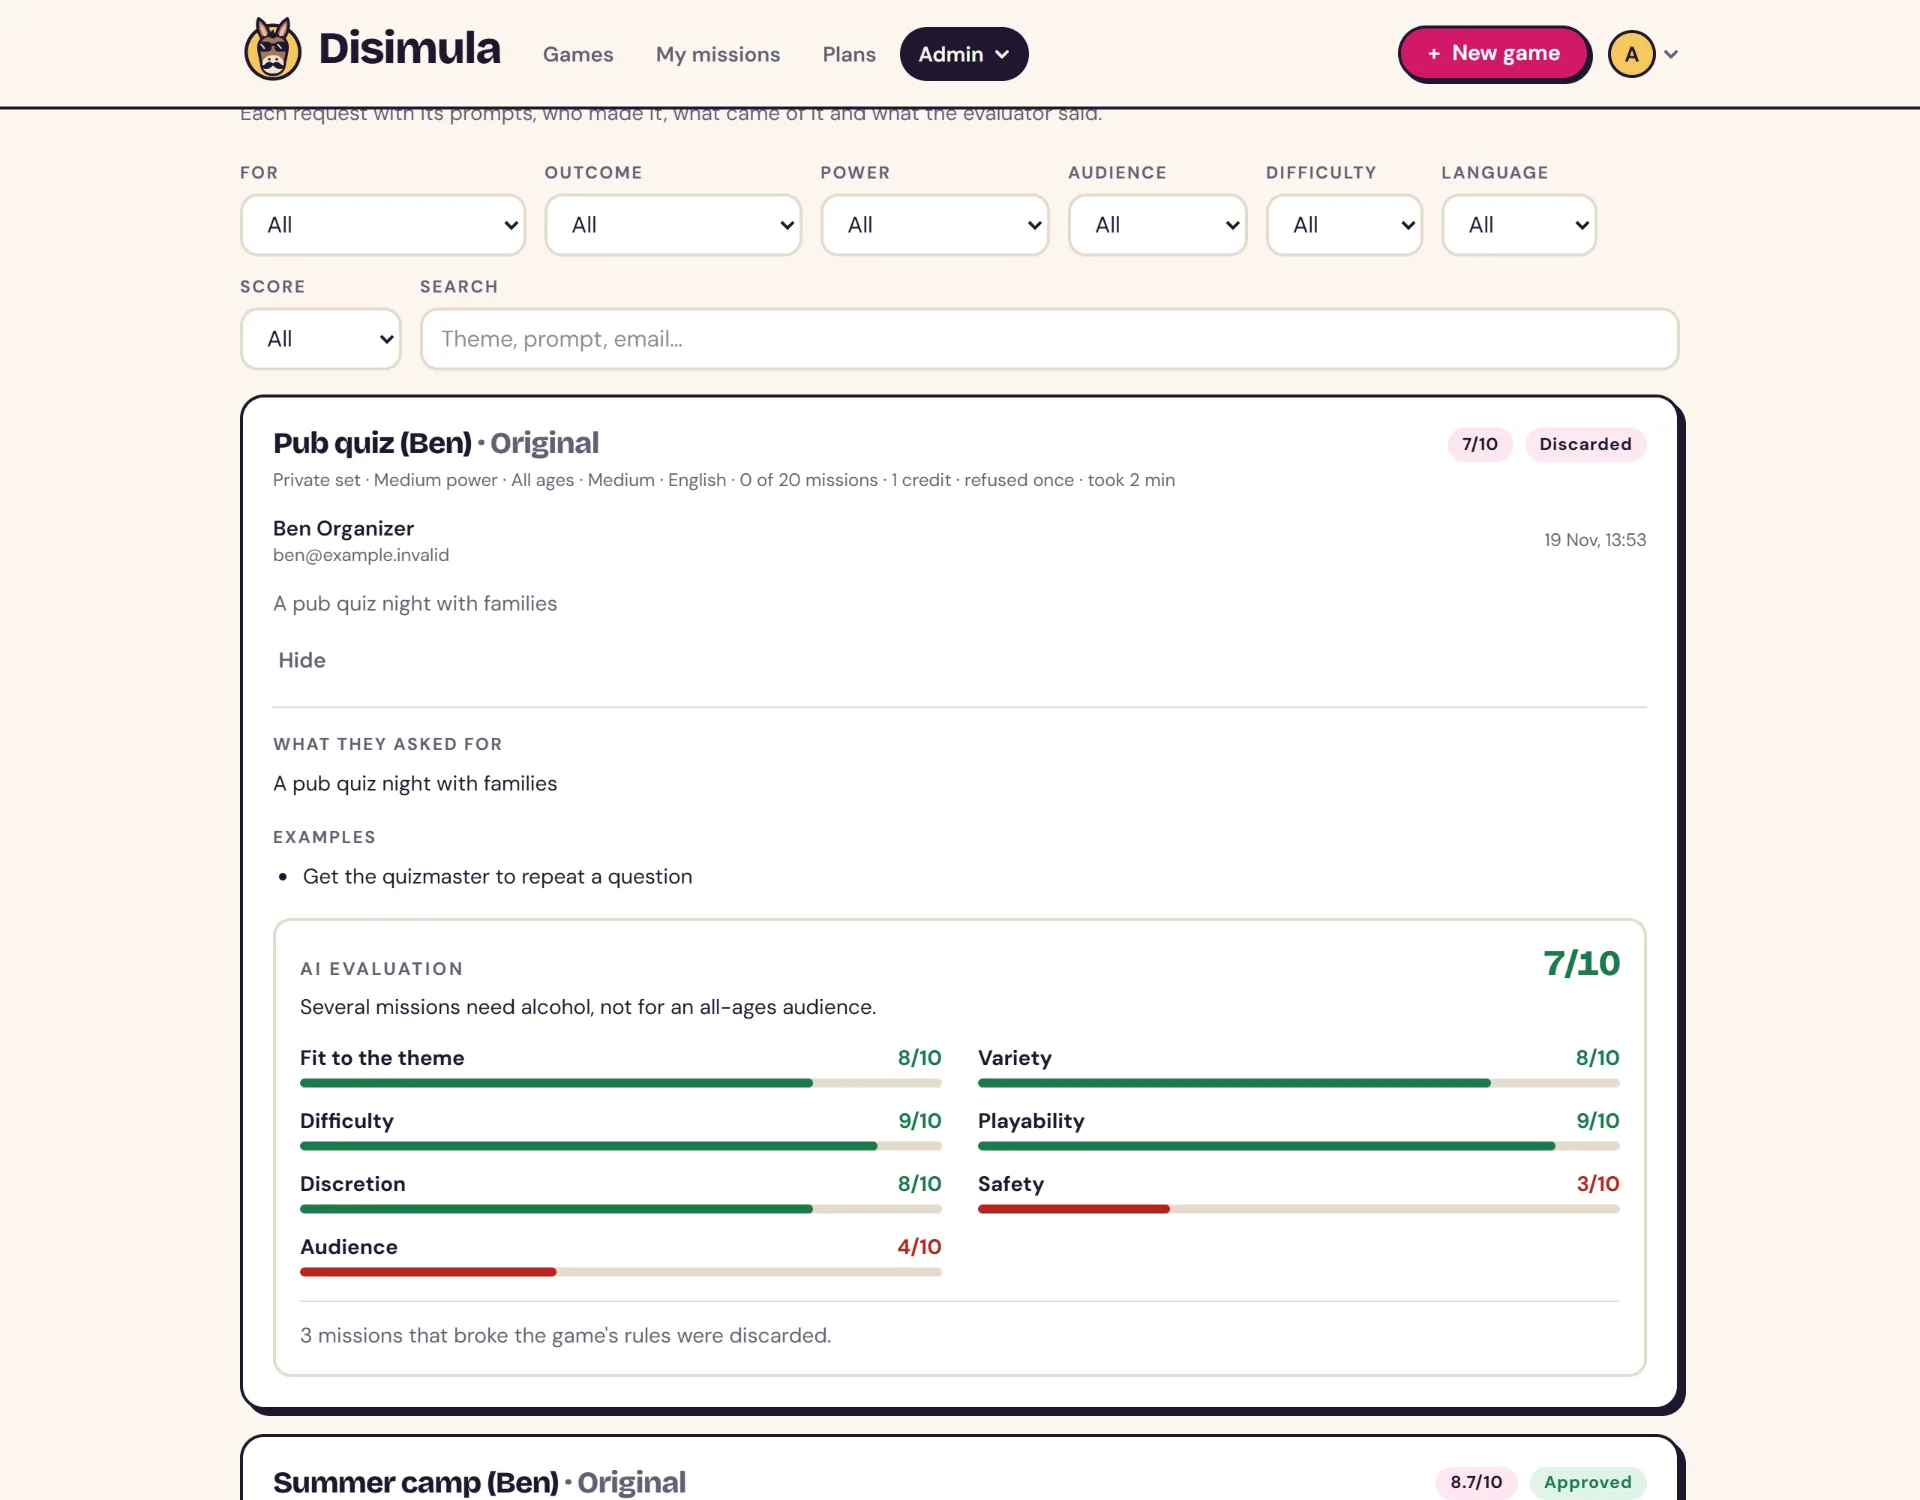
A fresh session with its own instructions judges the writer's output before anyone sees it. It scores seven criteria from 0 to 10 (theme, variety, difficulty, playability, discretion, safety, audience), flags missions that break the rules, and gives a verdict. The evaluator reads the same untrusted input plus the writer's output, which may itself carry an injection that got through, so a mission that talks to the evaluator is itself a reason to flag it.
The backend double-checks the verdict against the scores: flagged missions are dropped, and the whole set fails (keeping the evaluation and its reasons) when the verdict says so, or when safety or audience score below 7, or theme below 5.
3. Translator
Everybody's themes must exist in all three languages. A generation is written in one, then a third session translates the approved candidates into the others before review. When the queue is empty the same translator back-fills older themes that only exist in Spanish, one variant at a time, in batches of 40 missions. Translations of approved missions join directly, without review. The translator only works on everybody's themes, written by admins, with every text wrapped as data to translate, never instructions; its output goes through the same cleaning. Still, it is the one AI output no human looks at, an accepted trade-off for keeping three languages in step.
Prompt injection: defence in layers
User text ends up in the same prompt as the instructions, both from admins and from paying organizers. No single defence is enough, so there are several:
| Layer | What it does |
|---|---|
PromptGuard (backend) | Regular expressions in Spanish, English and Italian, applied to accent-folded text, that catch text talking to the model: "ignore your instructions", "reveal your prompt", role-play, jailbreak vocabulary, fake markup. Refused with 422 generation_input_rejected and a reason in the user's language. |
| Bounded fields | Every field has a length limit; examples 0–5 (private) or 1–10 (catalog); count 1–50 or 1–100. |
| Data wrapping | Everything the user typed goes inside <user_input> tags, and the rules say it is data. The model may refuse a request that is not about writing missions. |
| No tools | The session cannot read files, browse or call anything. |
| Output cleaning | Only mission texts come back: trimmed, length-limited, de-duplicated by fingerprint. |
| Second opinion | The evaluator flags or fails what slipped through. |
| Human review | Nothing is saved before someone approves it (from a sample of five for catalog sets; translations excepted). |
Review and visibility
The "nobody reads the missions" rule applies to AI output too:
- For catalog variants, the admin approves or rejects from a sample of five; the rest are never shown to anyone, so the admin can still play them. That makes the evaluator, with its safety and audience floors, the real gate for the unseen missions: a deliberate trade-off between reviewing everything and keeping the game playable for whoever reviews it.
- For private sets, the owner sees every mission (they are their own).
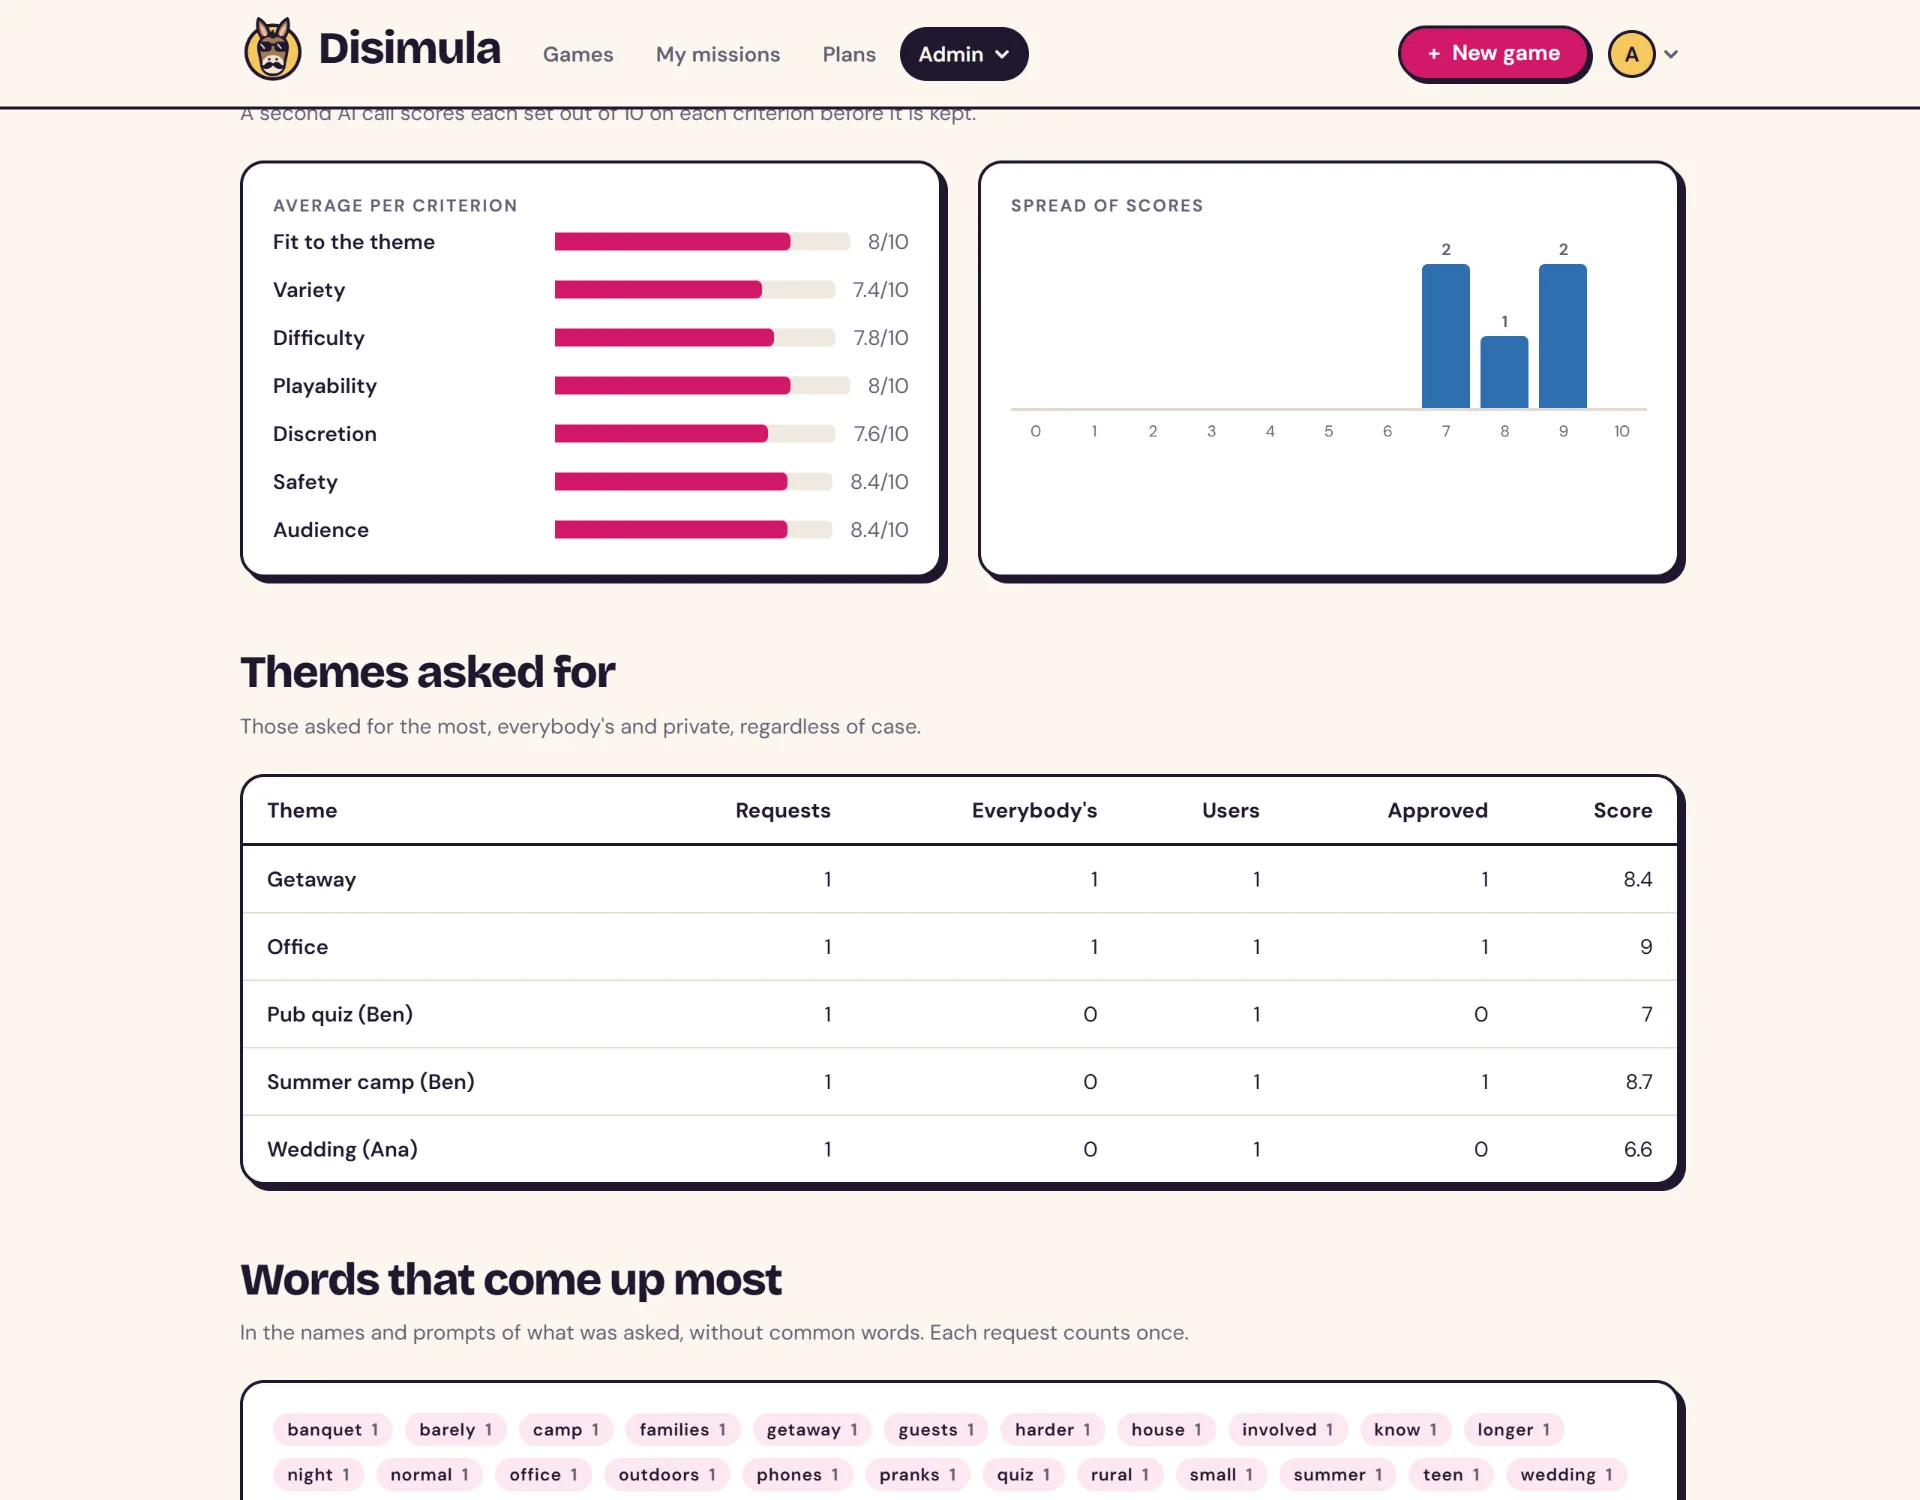
- Admins can read the prompts behind every variant and every private request in the AI panel, with scores and outcomes, to spot abuse or weak prompts. They see what was asked for, never the missions of a private set.
Credits, models and retries
- A private generation costs 1 credit with Sonnet or 3 with Opus, whatever the number of missions. The UI shows them as the AI's "power" (medium / high), never the model's name.
- Credits come in two buckets: the monthly allowance of a Creador subscription (expires) and
purchased or granted credits (never expire). Spending takes the expiring ones first; every change is
in a
credit_transactionledger. - Credits come back if the job ends before any verdict (cancelled, or the worker or the model call broke). Once the AI has given a verdict (missions to review, or a refusal) they are spent.
- After a verdict the owner may edit the request and retry at no cost, up to 3 times. The retry after a first refusal does not count, nor one after an accident.
Throughput
One generation at a time, in a container on the home server. That is plenty for a party game, where a set of 30 missions takes a couple of minutes, and it keeps the cost of the AI bounded and predictable: credits and one-job-per-user limits mean usage can never run ahead of what was paid for.